Turn written text into spoken audio
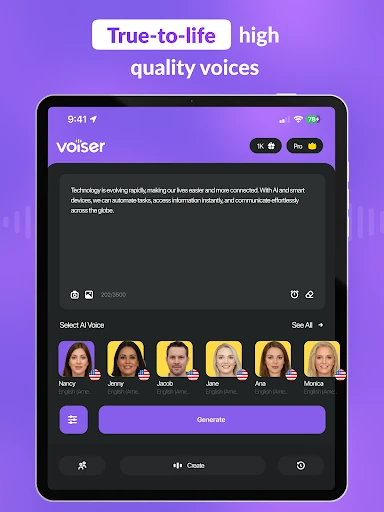
AI Voice: Text to Speech TTS converts typed text into voice recordings for users who need narration without recording it themselves. It suits content creators, students, educators, and anyone preparing spoken material for videos, podcasts, presentations, or other digital projects.
Useful for narration and accessibility
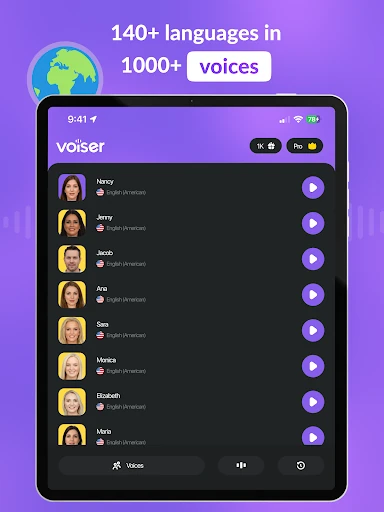
The app focuses on making text easier to hear and reuse. It can produce more natural-sounding speech than basic computer voices, helping users create voiceovers for short-form content, learning materials, and promotional work. Support for multiple languages and accents also makes it useful when one piece of content needs to reach different audiences.
Control over the result
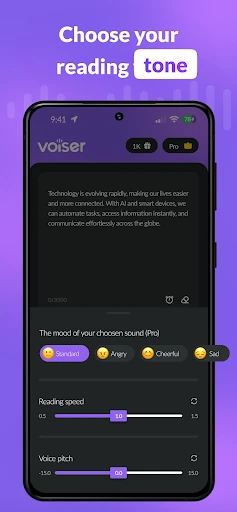
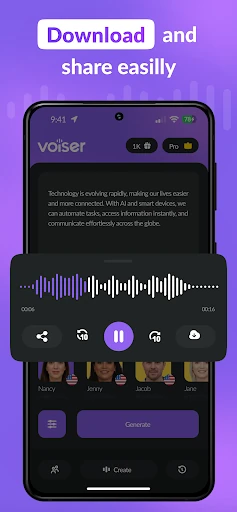
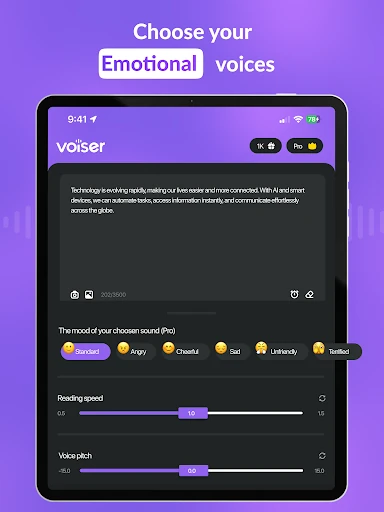
AI Voice: Text to Speech TTS includes options for adjusting elements such as speaking speed, pitch, and tone. These controls let users shape the delivery to better match the source text, whether the result should sound measured, energetic, formal, or suited to a particular project. Generated audio can also be converted for use with common editing workflows.
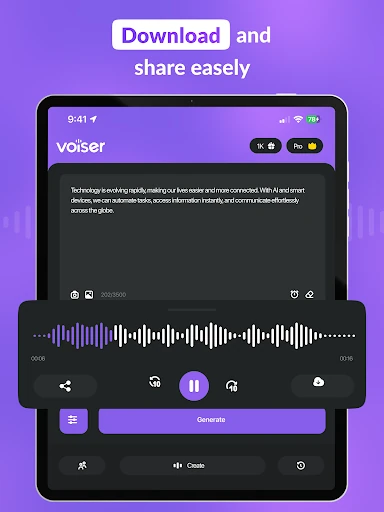
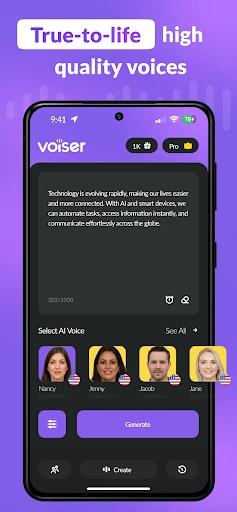
- Enter text and turn it into spoken narration.
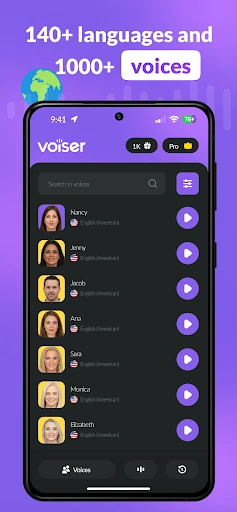
- Choose from available voices, languages, and accents.
- Adjust speech characteristics to fit the intended use.
- Prepare audio for videos, podcasts, lessons, and presentations.
Ratings and listing details
With a 4.32 rating from 29,585 reviews and more than 1,000,000 installs, the app has a substantial user base in the Productivity category. It is developed by Voiser Teknoloji Limited Sirketi. The range of voice and adjustment tools may be more than casual users need, but it gives regular creators room to refine spoken output instead of relying on a single default voice.